Zero-Shot Segmentation in Manufacturing: What It Can and Cannot Do

Segmentation has long been one of the most labor-intensive steps in a vision project. Every defect, component edge, or region of interest had to be outlined by hand, pixel by pixel, often across thousands of images.
Promptable foundation models changed that cost structure, at least in principle. An object can now be pointed at, or described, and a mask returned without task-specific training.
The question for quality and engineering teams is how much of that holds up on a real line. While zero-shot segmentation in manufacturing is useful for a defined set of jobs, it is unsuitable for others. This guide separates the two, explains why, and sets out a practical way to test it before anyone commits budget.

Key Takeaways

What zero-shot segmentation means in industrial inspection

Segmentation assigns each pixel in an image to a region: this area is the part, that area is a scratch, the rest is background. Traditional segmentation models learn those regions from hand-drawn masks on the exact task they will perform.
Zero-shot segmentation skips that task-specific training. A foundation model pretrained on a very large, general dataset is prompted at runtime with a point, a bounding box, or, in some setups, a text description, and returns a mask. The best-known example is Meta AI Research’s Segment Anything Model (SAM). Its authors assembled a dataset of over 1 billion masks on 11 million licensed images and trained the model to be promptable so that it transfers zero-shot to new image distributions and tasks.
That scale is the reason the approach generalizes. It is also the reason for caution. None of those images were taken on your line, under your lighting, of your product parts.

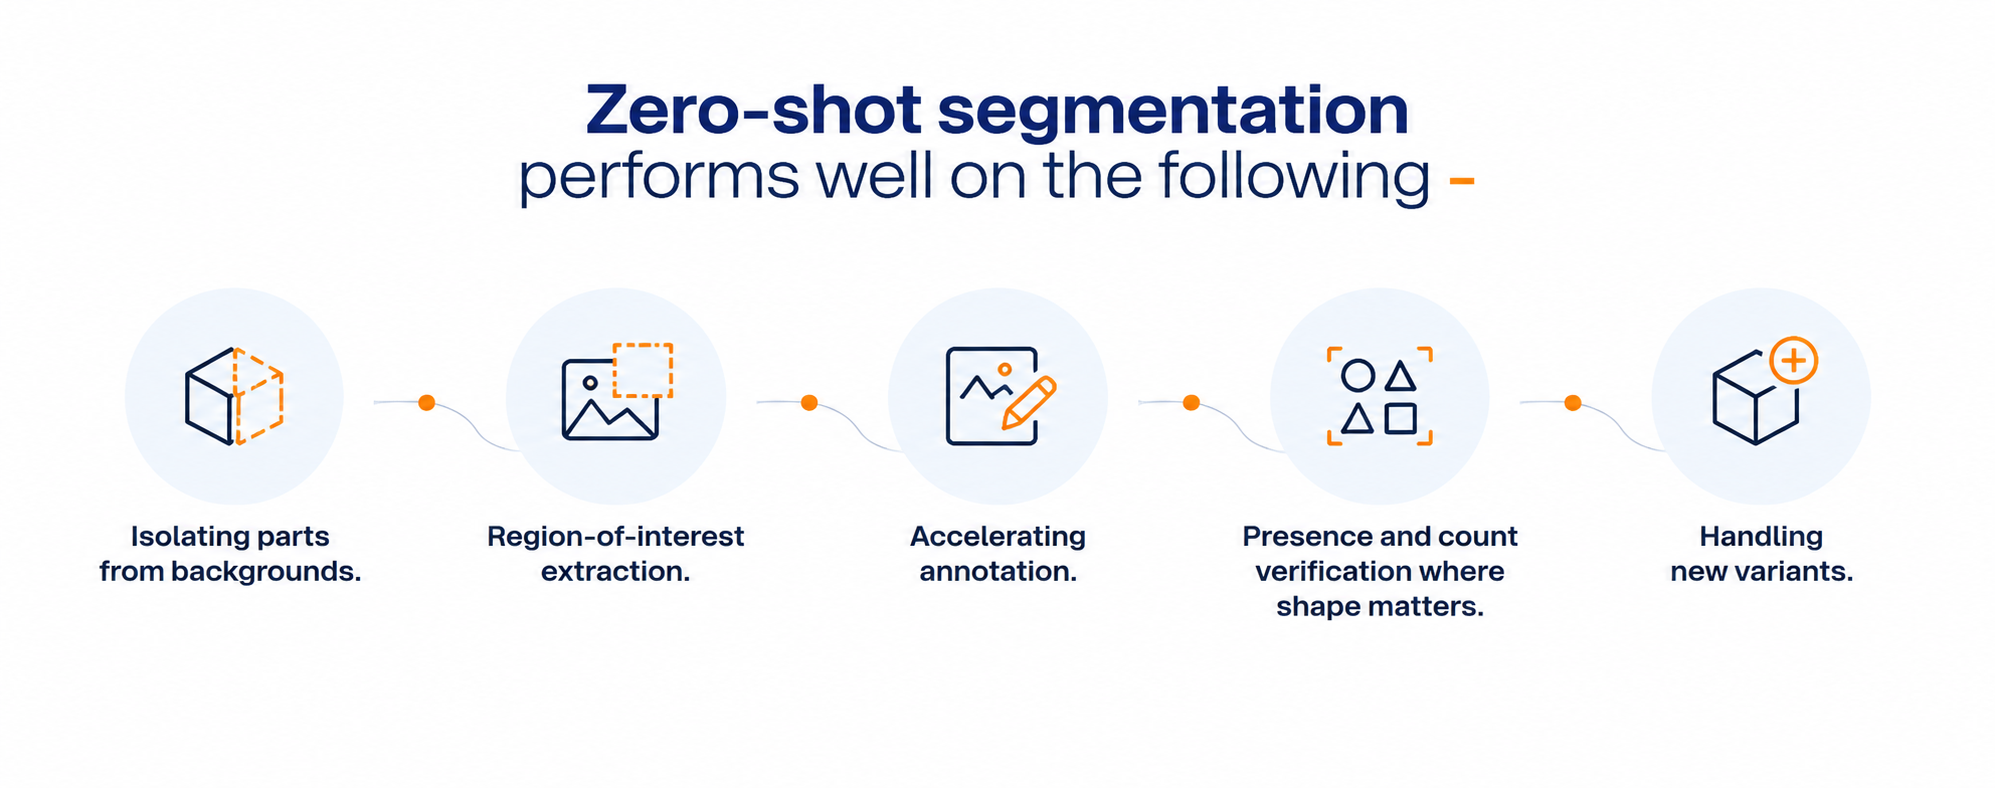
Where zero-shot segmentation performs well

The strongest fits share one trait: the region being segmented is visually distinct from its surroundings.
In each case, the model performs localization. It reports where something is. A separate step decides whether that something is acceptable.

Where zero-shot segmentation is unreliable
The limitations map closely onto the defect types manufacturers care about most.

Fine and low-contrast defects

Hairline cracks, micro-scratches, faint discoloration, and subtle porosity often lack clear edges. The SAM authors state that the model can miss fine structures, sometimes generates small disconnected components, and does not produce boundaries as crisply as more computationally intensive methods.[1] On a production line, a missed hairline crack is not a small error to be overlooked.

Acceptance criteria

A mask is not a verdict. The model can outline a mark on a surface without any sense of whether that mark is cosmetic, within tolerance, or cause for rejection. Acceptance criteria live in your quality system, not in a general-purpose model.

Consistency across imaging conditions

Glare, reflective metal, transparent packaging, and shifting ambient light can change results from one frame to the next. The absence of task-specific training does not reduce a model’s sensitivity to imaging conditions.

Speed at line rate

Large foundation models are computationally heavy. Where a decision must be made inside a single machine cycle, the full model may not keep pace without dedicated hardware or a lighter distilled version.

Zero-shot detection vs. segmentation: which does your inspection need?

The two terms are often blended, and the difference affects system design. Zero-shot detection in industrial inspection draws a box around a candidate and assigns a label. Zero-shot segmentation draws the outline. Detection is usually sufficient for presence, position, and counting, and it costs less to run. Segmentation earns its additional compute when shape, area, or boundary precision matters, such as measuring a coating gap or the extent of a surface defect.
Aspect Zero-shot detection Zero-shot segmentation
Output A box and a label A pixel-level outline (mask)
Best for Presence, position, and counting Shape, area, and boundary precision
Compute cost Lower Higher
Example Confirming a part is present Measuring a coating gap or defect extent
Teams often chain the two. An open-vocabulary detection model locates candidate regions from a text prompt in production, and a segmentation model outlines what sits inside each box.

Where does the Segment Anything Model (SAM) fit in manufacturing workflows?

The roles above differ mainly in how much human judgment sits between the mask and the decision, and that is what should order a SAM manufacturing rollout. Exploratory analysis of archived images carries no line risk, because nothing reaches production. Annotation assistance comes next, because an engineer approves every mask before it becomes training data. Preprocessing follows, since a trained classifier still makes the call on the cropped region.
A fourth role, treating the model as the final accept-or-reject authority, is where most disappointment occurs. It is rarely the right starting point.

How do vision-language models and segmentation models work together?

Foundation models for visual inspection increasingly work as a set rather than alone. A vision-language model can be asked whether an image shows anything unusual and to describe it. A segmentation model then outlines the region it points to. That pattern is behind most current interest in vision-language models for defect detection, particularly for unfamiliar anomalies. It also stacks two sources of uncertainty, so validation on your own images matters more.

How do you test zero-shot segmentation on your production line? 7 steps

A short, structured test answers most questions before a full project starts. Seven steps cover the ground.
  1. Assemble a hard evaluation set: Include your subtle defects, reflective parts, and worst lighting, not only clear examples.
  2. Define success in operational terms: Mask overlap scores are useful, but the decisive question is whether the mask would lead to the right part disposition: accept, rework, or reject.
  3. Compare prompt types: Points, boxes, and text prompts behave differently. Test the one you would actually use in production.
  4. Measure speed on target hardware: Benchmark on the device that would sit near the line, not a research workstation.
  5. Repeat across shifts and variants: Run the same prompts on images from different shifts, operators, lighting states, and a recent part variant, to see whether performance holds without adjustment.
  6. Record how it fails, not only how often: A model that misses in predictable ways is easier to manage than one that fails at random, and a clear list of what it misses is as valuable as an accuracy score.
  7. Check review time and traceability: If reviewing uncertain masks takes longer than manual inspection, the workflow needs redesign. Record model version, prompt, and image for each output so decisions can be audited later, a standard practice in production MLOps pipelines.
If a zero-shot model performs well only after heavy prompt tuning on a handful of images, run the same prompts on a fresh batch before trusting the result. Overfitting prompts is easier than it looks.

When should you move from zero-shot to a fine-tuned model?

Move beyond zero-shot when fine defects dominate, tolerances are tight, or decisions must be made within a machine cycle. Zero-shot segmentation for industrial inspection is often the fastest way to learn whether a computer vision inspection project is tractable, but it is not always the final answer. In those cases, the usual next step is fine-tuning on a modest set of your own images or distilling results into a smaller model.

How Intuceo approaches segmentation work

Intuceo starts with the inspection decision the business needs, then works backward to whether segmentation, detection, or a simpler rule is the right tool. Scope your inspection use case with an AI architect.

Two capabilities carry most of the delivery on vision work. High-fidelity visual inspection applies image segmentation, sub-pixel anomaly detection, and automated feature extraction to sub-millimeter defects, including precision medical optics, where surface anomalies, edge irregularities, and contaminants have to be caught at production speed. Multi-modal vision intelligence brings video, image, and metadata streams together so inspection results arrive alongside line system signals rather than in a separate console.

Deployment is the part that has to survive audit. Intuceo delivers in on-premise, private cloud, and air-gapped environments, driven by PhD-led engineering teams with prior deployments in regulated and high-precision environments. See how this applies across AI-driven advanced manufacturing and to the ML and computer vision capability built for it.
Join AI Dream Session, Vol. 2: Computer Vision Reimagined

AI Dream Session, Vol. 2: Computer Vision Reimagined is a 45-minute live session with Intuceo on Thursday, September 24, 2026, at 11:00 AM ET. It covers how newer vision models reduce dependence on large labeled datasets, and where accuracy and production conditions still create hard problems.

Frequently Asked Questions

It is the ability to outline objects or regions in an image using a pretrained foundation model, guided by a prompt such as a point, box, or text description, without training on your specific parts. In inspection, it is most often used to isolate components, extract regions of interest, and speed up labeling, rather than to make final quality decisions on its own.
Not entirely. They can sharply reduce the labeling needed to get started and can pre-label images for engineers to correct. You still need a labeled evaluation set from your own line to confirm performance, and many subtle defect types still benefit from fine-tuning on examples specific to your process.
Four limits dominate: weak performance on fine or low-contrast defects, no built-in understanding of acceptance criteria, sensitivity to glare and lighting changes, and heavy compute requirements for large models.
Yes, in well-chosen roles: annotation assistance, preprocessing that isolates parts or regions, and exploration of archived images. Using them as the sole accept-or-reject authority is riskier.
Not always. Large foundation models are computationally heavy, so decisions inside a single machine cycle may need dedicated hardware or a smaller distilled model.

A Decision Framework for Revisiting Shelved Computer Vision Inspection Projects in Manufacturing (2026)

Many plants carry at least one computer vision inspection initiative that cleared a pilot and then went quiet. The reasons were usually sound. The defect was too rare to build a training set. Parts changed faster than the model could be retrained. The labeling bill outgrew the savings, or integration with the line took longer than anyone had budgeted.
Vision models have moved on since then, and some of the constraints that stopped a computer vision inspection program in manufacturing have loosened-while others have not. For operations and quality leaders, the task is sorting shelved computer vision projects into three groups: the ones newer AI makes worth a revisit, the ones that need a scoped test first, and the ones that should stay exactly where they are. This framework is built for that sort.
KEY TAKEAWAYS

Why Computer Vision Inspection Projects in Manufacturing Get Shelved

Before scoring anything, name the real reason each project stopped. Most paused AI projects in manufacturing trace back to one of six causes:
The first three are data problems. The next two are engineering and operating problems. The last has nothing to do with technology at all. That distinction decides which projects newer models can realistically help.

What Has Changed in Manufacturing Computer Vision-and What Hasn’t

Foundation models pretrained on broad image collections have reduced the labeled data required by certain inspection use cases. Zero-shot and open-vocabulary approaches let teams describe what to look for rather than training a separate model for every defect category from scratch. 
Modern AI defect detection in manufacturing now includes these foundation models, which reduce the labeled data required for industrial inspection across a wider range of part types and defect categories.
Industrial anomaly detection also has a standard reference point. The MVTec Anomaly Detection benchmark, built specifically for industrial inspection, provides defect-free training images for each category and a test set containing both defective and defect-free images, with pixel-precise annotations of the anomalies. It holds more than 5,000 high-resolution images across fifteen object and texture categories. [1] 
That setup mirrors a common plant reality: plenty of good parts, very few bad ones. For manufacturing plants where visual inspection AI programs stalled because defects were rare, anomaly detection methods built around defect-free training images are worth a fresh look.

What has not changed

Better models do not fix optics. Poor lighting, glare, vibration, and inconsistent part positioning still break inspection. Large models can still be too slow for decisions inside a single machine cycle. Integration with manufacturing execution systems (MES) and programmable logic controllers (PLCs) still takes engineering effort. And a project without a clear owner on the plant floor will stall again, whatever model sits underneath.

Six Criteria for Evaluating a Paused Computer Vision Pilot

Use the table below to score each shelved project. It is designed to be completed in a working session with quality, operations, and data teams in the same room.
Criterion Question to ask Signal to revisit Signal to leave shelved
Original blocker Why did the project stop? Data scarcity, variation or labeling cost Business context changed or no owner
Value today Is the machine vision quality control gap still costing money in escapes, scrap or inspector hours? Escapes, scrap or inspector hours persist Line retired or defect designed out
Data on hand Do archived images still exist? Images and some confirmed defects available Nothing retained from the pilot
Speed requirement How fast must a decision happen? Seconds or sampled inspection is acceptable Hard real-time at very high line speed
Integration path Can results reach the line? Clear route to MES, PLC, or operator screen No path, and no budget to build one
Ownership Who will run it in production? Named quality or operations owner Only a data team champion
Score each row as a clear yes, partial, or no. Projects with strong answers on original blocker, value, and ownership are the best candidates, even if the other rows need work.

Sorting projects into three groups

Reopen now

These projects stopped because of data scarcity, part variation, or labeling cost, but still address a live problem and have a named owner. Archived images exist. Speed requirements are manageable. For these, zero-shot inspection or anomaly detection trained on good parts can often be tested within a short, contained assessment.

Reassess with a scoped test

Here the value is real, but one or two rows are uncertain. The line may run fast, or integration may have been the original sticking point. Run a focused test that answers the uncertain question directly, such as whether the model can meet cycle time on the current hardware, before committing to a restart.

Leave on the shelf

Some projects should stay paused. If the line was retired, the defect was designed out, or nobody in operations will own the result, better models change nothing. Closing these formally clears space for the candidates that matter.

A practical reassessment sequence

Deciding when to restart vision AI work is easier with a fixed sequence. The steps below keep the reassessment small and evidence-based.

Common mistakes when reopening a shelved project

Teams that restart vision work too quickly tend to repeat common errors. Watching for them saves a second shelving.

How to Rebuild the AI Visual Inspection Business Case for 2026

Old business cases carry old assumptions. Rebuilding AI inspection ROI for 2026 means checking which inputs have actually moved since the original approval:
One caution: a shelved project that looks attractive only because the new model was tested on easy images has been re-pitched rather than reassessed. Insist on the same difficult cases that stopped it the first time. Manufacturing defect detection AI that clears those, at production line speed and under production lighting, has earned a restart budget. Anything less has earned another test.

How Intuceo Approaches Computer Vision Inspection Reassessments

Reassessments run on the same structure Intuceo uses to judge any AI initiative before it reaches production. The DARWIN AI governance framework separates the question into dimensions that can each be answered independently:
A project can pass on model accuracy and still fail on three of those four, which is why the judgment is never made on a model alone.
For vision work, two capabilities carry most of the delivery. High-fidelity visual inspection applies image segmentation and sub-pixel anomaly detection to sub-millimeter defects, including precision medical optics, where surface anomalies, edge irregularities, and contaminants have to be caught at production speed. Intuceo’s multi-modal vision intelligence capability brings video, image, and metadata streams together so an inspection result lands alongside line system signals instead of a separate console-see how this is applied across our advanced manufacturing AI solutions.
Deployment is half of a reassessment that has to survive audit-a challenge Intuceo addressed directly in its advanced ML inspection pipeline case study. Intuceo delivers in on-premise, private cloud, and air-gapped environments, and client data is not used to train public models. For a plant that cannot accept a hosted model changing behavior between validation runs, that removes the variable rather than managing around it.
PhD-led engineering teams with prior deployments in regulated and high-precision environments deliver solutions to fit your unique needs. See how that applies across our advanced manufacturing AI solutions and to our computer vision and AI capabilities built for it.

Have a vision project sitting on the shelf?

AI Dream Session, Vol. 2: Computer Vision Reimagined is a 45-minute live session with Intuceo on Thursday, September 24, 2026, at 11:00 AM ET. It covers which previously rejected use cases may now be viable, where limitations still hold in production, and the questions worth asking before any project is reopened.
Get the reassessment questions before your next project review

Frequently Asked Questions

A shelved vision project is worth revisiting if it originally failed due to data scarcity, part variation, or labeling cost-not due to line speed limits, integration barriers, or lack of ownership. Start with the reason it stopped. If the blocker was too few defect examples, frequent part variation, or labeling cost, newer vision AI models may help. Then test on archived images from the original pilot, measured against the original acceptance criteria. If the blocker was line speed, integration, or lack of ownership, better models alone are unlikely to change the outcome.

Six criteria determine whether a paused computer vision project is worth restarting in manufacturing:
(1) original blocker,
(2) current cost of the problem, (3) availability of archived images,
(4) line speed requirements,
(5) integration path to MES or PLC, and
(6) named operational ownership. Projects that score well on blocker, value, and ownership are usually the strongest candidates.

Four inputs in an old computer vision inspection business case are worth re-checking in 2026: labeling effort (often lower for foundation model use cases), retraining frequency (potentially less frequent where models generalize across part variants), compute cost per image (potentially higher with larger models at the line), and the value of catching a defect (unchanged-set by your process, not by the model). Re-check the first three against your own parts before any approval, and leave the fourth where the original case had it.

Revisit the ones canceled for data or variation reasons, where the underlying problem still exists, and a plant owner is ready to run the result. Leave closed the projects whose lines were retired, whose defects were designed out, or that lacked operational ownership. A short, documented reassessment is the fastest way to tell the difference.